👩🏼🏫 Invited talk at Intelligent things
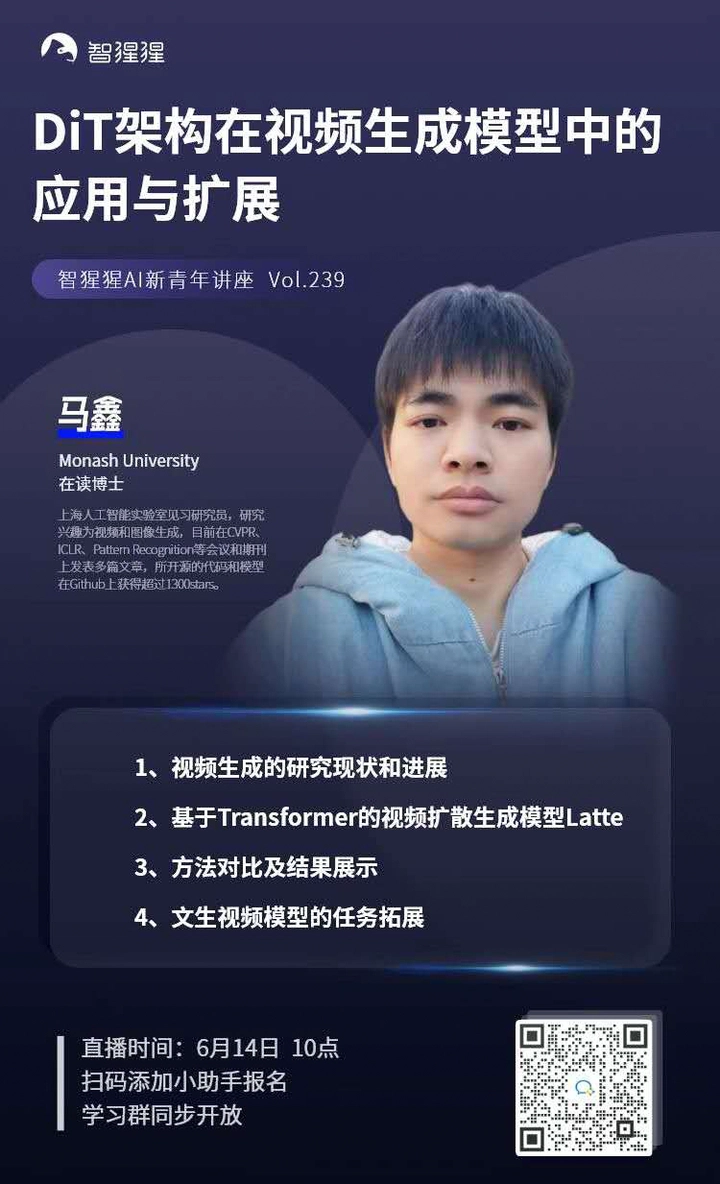
I have been invited to give a talk on “Application and Expansion of the DiT Architecture in Video Generation Models” at Intelligent Things.
Abstract
In this talk, I will share the current state and recent advances in video generation research. I will then introduce Latte, a Transformer-based video diffusion model. Following that, I will present some visual comparisons of generated videos. Finally, I will conclude with a discussion on potential future directions and task extensions in text-to-video generation.

Xin Ma
PhD
My research interests include world models, video and image generation, model efficieny, and so on.